Cloud 3.0 and Geopatriation

To understand where cloud is going in 2026, it helps to see where it’s been — because the change underway is a genuine paradigm shift, not an incremental one.

Diagram illustrating the three eras of cloud computing: Cloud 1.0 'Migration' focuses on infrastructure as a service (IaaS); Cloud 2.0 'Cloud-native' emphasises hyperscaler-centric services; Cloud 3.0 'Sovereignty-first' prioritises hybrid and multi-cloud solutions with an emphasis on jurisdiction and control.

Cloud 1.0 — migration. Organisations moved to the cloud to shed the “undifferentiated heavy lifting” of managing hardware. The question was simply can we run this in the cloud? — lift-and-shift, IaaS, someone else’s servers.

Cloud 2.0 — cloud-native. The era of “cloud first.” Teams rebuilt around managed services, autoscaling, and the seemingly infinite capacity of a handful of hyperscalers. The question became how fast can we scale? Concentration on a few global providers was a feature, not a worry.

Cloud 3.0 — sovereignty-first. As we move through 2026, the primary driver is no longer “the cloud as a place to run code” but “the cloud as a jurisdictional and strategic asset.” Organisations are no longer content to have their data “somewhere in the ether” — they need to know exactly which laws govern it, who has the technical ability to access it, and how it fits an increasingly fragmented global regulatory landscape. The defining question is now where, and under whose laws, does this run?

Cloud 3.0 is characterised by a small set of ideas that separate it from its predecessors: sovereignty (data under local or regional control), resilience (designed to keep working through disruption), hybrid flexibility (workloads move between private, public, and edge), built-in compliance (governance is part of the architecture, not bolted on afterward), and AI readiness (built to support training and real-time inference). Instead of depending mainly on large public clouds, organisations are adopting a more balanced model spanning hybrid, multi-cloud, sovereign, and edge.

Geopatriation: the defining 2026 trend

The strategic move at the centre of Cloud 3.0 has a name. Gartner identified “geopatriation” as a defining enterprise trend for 2026: the deliberate shift of data and workloads from global public clouds to local sovereign or regional alternatives.

It’s worth distinguishing geopatriation from plain cloud repatriation. Repatriation, the older idea, is mostly cost-driven — pulling workloads back to on-prem to escape unpredictable bills. Geopatriation is jurisdiction-driven — the strategic relocation of critical workloads to local or private infrastructure (or nationally hosted “sovereign enclaves”) to control which laws and which governments can reach them. Crucially, it is not an abandonment of the cloud — it’s a refinement of it. Most companies aren’t deleting their AWS accounts; they’re deciding which workloads belong where. The conversation has shifted from whether to localise to which workloads to localise first.

The market signals are not subtle. Worldwide sovereign cloud spending is forecast to reach $80 billion in 2026 — a 35.6% jump from 2025. Gartner reports 61% of European CIOs want to reduce dependency on US cloud providers; Accenture finds 62% of EU organisations actively seeking sovereign solutions — against a backdrop where US hyperscalers hold roughly 70% of the EU cloud market. And three-quarters of business leaders say they’re concerned about the geopolitical risks of storing data in global clouds. Cloud strategy has moved from an IT decision to a boardroom one.

The forces driving it

Five forces converge to push workloads toward sovereign and regional providers. As a developer or architect, you’ll feel all of them as requirements landing on your roadmap.

Infographic illustrating the forces driving geopatriation, including geopolitical tension, legal issues, regulation, shifts to sovereign providers, the AI data grab, and costs associated with cloud services.

Geopolitical tension. Trade wars, export controls, digital sanctions, and a fragmenting “splinternet” make relying on a provider headquartered in another country a genuine strategic risk. If geopolitics sours, your infrastructure shouldn’t be a hostage.

Legal and extraterritorial access. The US CLOUD Act lets US authorities compel US-headquartered providers to hand over data regardless of where it’s physically stored, and the collapse of the EU-US Privacy Shield (the Schrems saga) underscored the exposure. Enterprises increasingly want environments governed solely by local law, with guarantees against external authorities.

Regulation. GDPR, the financial-sector DORA, the network-security NIS2, and the EU AI Act are making sovereign or residency-controlled hosting mandatory for specific workloads — and the proposed EU Cloud and AI Development Act (expected Q1 2026) aims to triple EU data-centre capacity to support it. For regulated buyers, your sovereignty posture now affects whether they can even purchase from you.

The AI data grab. This one is newer and underappreciated. Public providers increasingly use the data on their platforms to train their own models — so if your “secret sauce” lives on a public cloud, it can effectively be donated to the broader model (and your competitors). For proprietary datasets, that’s an unacceptable leak.

Cost. The classic repatriation driver still applies: the “cloud tax” of escalating egress fees and unpredictable consumption volatility pushes high-volume workloads toward more predictable, locally-controlled infrastructure.

The reframe: cloud as strategic territory

Put these together and the mindset shift is clear: the move from “Cloud First” to “Sovereignty First.” The cloud is no longer a featureless utility you rent by the hour; it’s regulated, strategic territory with borders, jurisdictions, and access rules that matter to your business and your compliance officer alike. Navigating it is no longer a purely technical challenge — it’s a risk-management priority that happens to land on engineers to implement.

This doesn’t mean the hyperscalers lose. It means the default of “throw everything in one global public cloud and scale” is over. The winning pattern is deliberately placing each workload where it belongs — public cloud for scale, sovereign or private for sensitive data and IP, edge for latency — and being able to prove which laws govern what.

The Hybrid Sovereign model

The architecture most enterprises are converging on is “Hybrid Sovereign”: use public clouds for scale, and sovereign or private environments for sensitive IP and regulated data. It’s the end of “one-size-fits-all” infrastructure in favour of routing each workload by its sensitivity, compliance exposure, and latency needs.

Diagram of the Hybrid Sovereign architecture, showing the workload classification layer that routes workloads based on data sensitivity, regulatory exposure, and latency needs. It includes sections for Public cloud, Sovereign/private control, Edge/regional proximity, Customer-held keys, and Confidential computing.

The three destinations:

  • Public cloud — for scale. Non-sensitive workloads, front-end web hosting, global content delivery, and elastic burst capacity. This is where the hyperscalers’ breadth and economics still win.
  • Sovereign or private — for control. Mission-critical IP, personal data (PII), and regulated workloads that must be governed under local law and shielded from foreign access.
  • Edge and regional zones — for proximity. Latency-sensitive and localised processing kept close to users, which also helps keep data within a jurisdiction.

The encouraging part for engineers: the cloud-native skills you built in the Cloud 2.0 era still apply. What changes is where each workload lands and who can technically reach it — a placement and governance problem layered on top of the same containers, pipelines, and services.

The three layers of sovereignty

Here’s the distinction that separates real sovereignty from marketing, and the single most important concept in this post for an architect to internalise. “Sovereign” is not one thing — it’s three escalating layers, and vendors blur them constantly.

Infographic illustrating the three layers of sovereignty: Operational sovereignty, Data sovereignty, and Data residency, with warnings about 'sovereignty-washing'.
  1. Data residency — your data is physically stored in a chosen region. This is table stakes: standard cloud regions already offer it, and on its own it is not sovereignty. Residency answers “where are the bytes?” — not “who can compel access to them?”
  2. Data sovereignty — the data is governed solely by local law. This adds legal control: which jurisdiction’s rules apply.
  3. Operational sovereignty — the environment is operated by local personnel under local jurisdiction, with technical controls preventing outside access — even by the provider’s own staff, even under a foreign legal order. This is the bar that actually answers the CLOUD Act concern.

The trap is “sovereignty-washing”: marketing data residency as full sovereignty. And even genuine local providers aren’t automatically immune — an EU-native provider was reportedly subject to a Canadian court order, a reminder that corporate structure and legal exposure matter as much as where the servers sit. The rule: verify technical controls; don’t trust contractual promises alone.

The offerings (as of 2026)

The hyperscalers responded with distinct architectures, and the differences map directly onto those three layers.

  • AWS European Sovereign Cloud (ESC) — generally available January 15, 2026, a €7.8 billion investment. It’s a new, fully independent AWS partition operated, governed, and controlled entirely within the EU: its own control planes, IAM, billing, and metadata handling, run by EU-resident personnel under a German parent entity. It launches with ~90 services and Local Zones in Belgium, the Netherlands, and Portugal. This reaches operational sovereignty — the most isolated option among the US hyperscalers — and crucially, its Nitro Enclaves provide hardware-enforced confidential computing that even AWS operators cannot bypass, independently reviewed by NCC Group. That last point matters: it makes the sovereignty claim verifiable rather than just a policy.
  • Microsoft — a layered approach: an EU Data Boundary, a European board, a “Data Guardian” approval system, and national partner clouds run by European joint ventures. In February 2026 it added M365 Local and Foundry Local, bringing productivity software and AI inference onto customer-owned hardware, disconnected from the public cloud — plus a commitment to in-country Microsoft 365 Copilot processing for 15 nations by end of 2026, and a Sovereign Landing Zone for workload classification and residency policy.
  • Google — Distributed Cloud (air-gapped) delivers environments fully disconnected from the internet and public cloud, so you can run AI and analytics on highly sensitive data, plus a partner-operated model for jurisdictions requiring local operation.
  • Oracle — an EU Sovereign Cloud with EU-resident operations.
  • EU-native providers — Hetzner, OVHcloud, Scaleway, and T-Systems offer European-headquartered alternatives, attractive when reducing exposure to US corporate jurisdiction is the goal (with the OVHcloud court-order nuance above as a caution that “EU-native” still needs due diligence).
  • GAIA-X — the broader European federated-cloud initiative aiming for interoperable, sovereignty-respecting infrastructure across providers.

The engineering controls that make it real

Sovereignty isn’t only contracts and corporate structure; it’s enforced in code and silicon. Two technical controls do the heavy lifting, and both are things you implement.

Confidential computing — protect data in use. Encryption at rest and in transit is standard; the gap was always data during processing, when it sits decrypted in memory. Confidential computing closes it with hardware-enforced enclaves (AWS Nitro Enclaves, Intel SGX/TDX, AMD SEV) that isolate computation and provide cryptographic attestation of code integrity — so sensitive data can be processed in an environment the provider’s own operators cannot read. This is what lets you run sensitive analytics or AI on infrastructure you don’t fully own.

Key-first security — BYOK / HYOK. The decisive question for access control is who holds the keys? A “key-first” policy ensures that your organisation — not your provider — holds the ultimate power over data access. With Bring-Your-Own-Key (BYOK) or Hold-Your-Own-Key (HYOK), encryption keys live in a key store you control; if the provider can’t decrypt without your key, a legal order served on the provider yields ciphertext. Combined with confidential computing and residency, key-first control is how operational sovereignty becomes technically true rather than merely promised.

A useful way to enforce residency at the architecture level is policy-as-code — the same governance-in-the-pipeline discipline, pointed at jurisdiction:

def admit_deployment(workload, target_region, policy) -> bool:
cls = classify(workload) # public / sovereign-required / air-gapped
if cls == "air-gapped" and target_region.connected_to_internet:
return reject("air-gapped workload cannot deploy to a connected region")
if cls == "sovereign-required" and target_region.jurisdiction not in policy.allowed_jurisdictions:
return reject(f"data residency violation: {target_region.jurisdiction}")
if cls != "public" and not workload.keys.customer_held:
return reject("sensitive workload requires customer-held keys (BYOK)")
return True # placement satisfies residency, jurisdiction, and key policy

The gate is deliberate: a workload’s classification, not a developer’s convenience, decides where it can land.

The AI placement problem

The core architectural decision is where each part of the AI lifecycle runs, and the answer isn’t one place — it’s a deliberate split by two axes: how sensitive the data is, and how compute-intensive the work is.
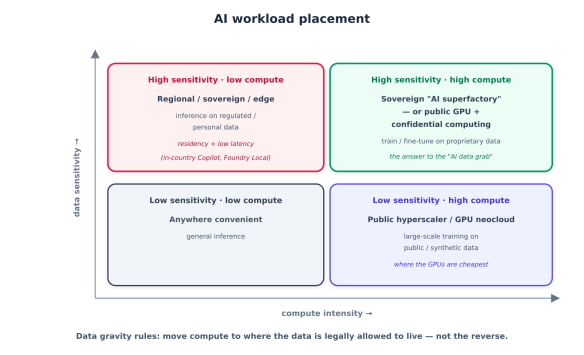
A chart detailing AI workload placement based on data sensitivity and compute intensity, divided into four quadrants: High sensitivity - low compute, High sensitivity - high compute, Low sensitivity - low compute, and Low sensitivity - high compute. Each quadrant includes descriptions of use cases and examples.

Reading the quadrants:

  • High compute, low sensitivity (large-scale training on public or synthetic data) → run it where the GPUs are cheapest and most plentiful: public hyperscalers or GPU-rich “neoclouds” (regional specialist GPU providers). Sensitivity is low, so cross-jurisdiction compute is acceptable.
  • High compute, high sensitivity (training or fine-tuning on proprietary data) → this is the hard quadrant. Options: a sovereign or private “AI superfactory” where proprietary datasets fine-tune models without ever touching the public internet, or public GPUs wrapped in confidential computing so even the provider can’t read the data in use. This is the direct answer to the “AI data grab”.
  • High sensitivity, low compute (inference on regulated or personal data) → regional, sovereign, or edge infrastructure for both residency and latency. Microsoft’s in-country Copilot processing and Foundry Local (on-device inference) exist precisely for this.
  • Low sensitivity, low compute → run it wherever is convenient.

The organising principle is data gravity: it’s far easier to move compute to where data is legally allowed to live than to move regulated data to where the compute is. Architect AI systems so the data anchors the placement, not the other way around.

Sovereign AI is the macro trend behind this: nations and enterprises building local AI capacity so that strategic compute and sensitive data stay within their borders — and AI-optimised sovereign environments (and neoclouds) are emerging to serve exactly that demand.

The geopatriation playbook

Here’s the actionable part — the roadmap practitioners are converging on for executing geopatriation without breaking what works or trading one lock-in for another.

Infographic titled 'The geopatriation playbook', outlining six steps for managing data workloads, including auditing dependencies, classifying workloads, designing for exit, implementing confidential computing, adopting key-first security, and building compliance.
  1. Audit for dependency. Map your data flows and the jurisdictions they cross, and identify “locked” workloads — the ones wired so tightly to proprietary managed services they can’t easily move. You can’t relocate what you can’t see.
  2. Classify workloads. Tier each workload by data sensitivity, regulatory exposure, and latency need into public-OK / sovereign-required / air-gapped. This is the “which workloads first” decision, made concrete — and it’s the input to the placement gate.
  3. Design for exit. The antidote to lock-in (including lock-in to a sovereign provider): containers and Kubernetes, open standards, infrastructure-as-code, and abstraction layers over provider-specific services where exit matters. “Exit architecture” means you can move a workload if jurisdiction, price, or geopolitics forces it.
  4. Implement confidential computing. Protect data during the high-value processing phase, not just at rest and in transit — the enclave-and-attestation pattern.
  5. Adopt key-first security. Hold your own keys (BYOK/HYOK) so you, not the provider, hold ultimate power over access. A legal order served on a provider that can’t decrypt yields nothing useful.
  6. Build in compliance. Enforce residency and jurisdiction with policy-as-code, mapping workloads to the regulations that bind them (GDPR, DORA, NIS2, EU AI Act). Governance belongs in the pipeline, not in a quarterly audit — the same “built-in, not bolted-on” principle that runs through the security and provenance themes.

The honest trade-offs

A credible playbook names its costs, and geopatriation has real ones. Don’t let the strategic urgency stampede you past them.

  • The sovereignty tax. Sovereign environments typically offer fewer services, higher cost, slower feature rollout, and smaller GPU pools than the global commercial regions. AWS ESC launched with ~90 services versus the full commercial catalogue; sovereign AI capacity is scarcer than hyperscale. Sovereignty buys control at the price of some capability and economics — budget for it.
  • Sovereignty isn’t binary, and “sovereign” is marketed loosely. Re-apply the test: residency ≠ operational sovereignty, and even EU-native providers can face foreign legal orders. Verify technical controls (independent review, hardware attestation), not just contractual language.
  • Complexity is the hidden bill. Multi-partition and multi-cloud operations mean separate control planes, IAM, billing, and tooling (AWS ESC is a wholly separate partition, by design). Fragmentation costs skills, money, and operational surface area. Multi-cloud is not free resilience — it’s deliberate engineering with real overhead.
  • Don’t over-rotate. Geopatriation is selective refinement, not a wholesale cloud exit. The whole point of Hybrid Sovereign is that most workloads stay on public cloud for scale; you move the ones where jurisdiction, IP, or regulation justify the tax. Resist the temptation to “sovereign everything” — it’s expensive and usually unnecessary.

The whole picture

Step back and the three parts form one architecture for the 2026 cloud. Cloud became a jurisdictional and strategic asset (Cloud 3.0), and geopatriation — moving workloads to sovereign and regional providers — is the defining response to geopolitical, legal, regulatory, AI-data, and cost pressures. The architecture is Hybrid Sovereign, routed by workload classification across public, sovereign, and edge, with sovereignty understood as three layers (residency → data → operational) and made real by confidential computing and key-first control. AI is the hardest case — placed by data sensitivity and compute intensity, anchored by data gravity — and the geopatriation playbook (audit, classify, design for exit, confidential computing, key-first, built-in compliance) executes it without trading scale for a new lock-in.

The strategic truth underneath: in a fragmenting world, where your workloads run, and under whose laws, is now an architectural decision with business and compliance consequences — and increasingly an AI decision, since the most valuable models are trained on the most sensitive data. The teams that map their jurisdictional dependencies, classify deliberately, and design for exit will move fast and stay compliant. The ones who treat the cloud as a borderless utility will discover, at the worst possible moment, that it never was.

Digital Provenance as a Trust and Compliance Requirement

For most of computing history, trust was implicit. You installed the package from npm because it was on npm. You believed the photo in your feed because photos were hard to fake convincingly. You trusted the data in your warehouse because someone you knew had loaded it. None of that trust was verified — it was assumed, because forging the alternative was expensive or obvious.

That assumption has collapsed on three fronts simultaneously, and the collapse is why digital provenance — the verifiable record of a digital asset’s origin, authorship, modifications, and chain of custody — has gone from a niche concern to, in Gartner’s framing, one of the Top 10 Strategic Technology Trends for 2026. The same analysts estimate that organisations that fail to invest in provenance by 2029 face sanction risks potentially in the billions. This is no longer just good hygiene; it’s becoming a trust differentiator and a hard compliance requirement.

Three collapses, one cause

Software. Attackers learned that the cheapest way into thousands of organisations is through the build pipeline, not the firewall. SolarWinds, Log4Shell, CodeCov, and the 2025 GhostAction campaign all showed the same thing: a compromised build or a typosquatted dependency reaches every downstream consumer at once. Knowing what is in your software stopped being enough; you now have to prove where it came from and how it was built.

AI-generated content. Synthetic media went from a curiosity to a flood. Deepfake incidents grew roughly 900% from 2023 to 2025 (one count puts it at over 8 million incidents in 2025), and analysts project synthetic content could account for up to 90% of online media. When anyone can generate an indistinguishable image, video, voice, or document, “seeing is believing” is dead. You need a way to know what’s real that doesn’t depend on the content looking real.

Data. As data feeds analytics, decisions, and — increasingly — AI model training, “where did this data come from, and can I trust it?” became a question with legal and financial weight: copyright, consent, contamination, and auditability all hang on it.

The common cause beneath all three: the cost of forging a convincing fake dropped to near zero, so trust now has to be proven rather than assumed. Provenance is how you prove it.

Diagram illustrating three domains: Software, AI-generated content, and Data, each with associated threats and the central concept of verifiable origin and integrity.

Provenance vs. lineage: a distinction worth getting right

Two terms get used loosely, and developers should keep them separate. Provenance answers “is this authentic, and where did it come from?” — proof of origin, authorship, and integrity. Lineage answers “how did this move and transform?” — the flow of data or an artifact across systems. Provenance is about trustworthiness at a point; lineage is about the path. You generally need both: provenance to decide whether to trust the source, lineage to understand the downstream blast radius if you can’t. This post is about provenance, but the two interlock constantly, especially for data.

What regulation just did to the timeline

Adoption was already growing; regulation fixed the deadline. The compliance clock is concrete and, as of 2026, largely already running:

  • EU AI Act, Article 50 — enforceable from August 2, 2026 — requires deployers of AI systems to disclose when content has been artificially generated or manipulated, using both visible markings and machine-readable metadata.
  • US Executive Order 14028 requires federal software suppliers to provide verifiable provenance, and the EU Cyber Resilience Act imposes similar build-integrity obligations on software sold in the EU.
  • California SB 942 (the AI Transparency Act) took effect in January 2026, with the New York Stop Deepfakes Act and others following.
  • The US CISA endorsed content credentials as a key countermeasure in a January 2025 advisory on multimedia integrity, recommending adoption by government and critical-infrastructure operators.

If you ship software to governments, or produce AI-generated content for public distribution, or handle regulated data, provenance is no longer optional — it’s an audit item.

The five primitives behind all of it

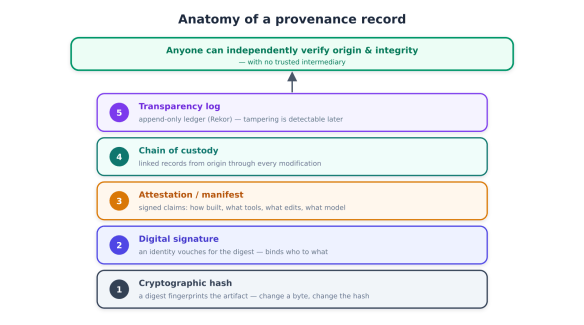
Here’s the unifying insight for developers, and the reason this is one post and not three unrelated ones: whether you’re vouching for a container image, a dataset, or a photograph, the cryptographic machinery is the same. A provenance system is built from five primitives stacked together.

An infographic titled 'Anatomy of a provenance record' outlining five key components: Transparency log, Chain of custody, Attestation/manifest, Digital signature, and Cryptographic hash, with a focus on independent verification of origin and integrity.
  1. Cryptographic hashing. A digest (e.g. SHA-256) of the artifact is its tamper-evident fingerprint: change one byte and the hash changes. This is how integrity is checked — the digest is the artifact’s identity.
  2. Digital signatures. A key (tied to an identity) signs the digest, binding who vouches for this to exactly this artifact. A valid signature means an identity stood behind this specific bytes.
  3. Attestations / manifests. Signed metadata that makes claims about the artifact — how it was built, which tools touched it, what edits were applied, what model generated it. This is where “provenance” becomes rich rather than just “unchanged.”
  4. Chain of custody. Linked records connecting the artifact from its origin through every modification to its current state, so the whole history — not just the latest step — is verifiable.
  5. Transparency logs. A tamper-evident, append-only public ledger (the model Sigstore’s Rekor uses) records signing events, so tampering or backdated claims can be detected even if a key is later compromised.

Stack these and you get the property that matters: anyone can independently verify origin and integrity, without trusting an intermediary. That independent verifiability is what separates real provenance from a metadata field anyone could fake.

The honest framing, set up front

One caution belongs at the start, not buried at the end, because it’s the most misunderstood point about provenance: provenance certifies history, not truth. A provenance record can prove that a specific tool signed a specific artifact and that it hasn’t been altered since. It cannot prove that the claim made is true — that the camera was pointed at what the caption says, that the dataset was collected ethically, that the code does what it claims. Provenance establishes that a claim was made and the artifact wasn’t tampered with afterward. It provides transparency, not judgement. Build with that boundary in mind and provenance is powerful; forget it and you’ll over-trust a green checkmark.

Why SBOMs aren’t enough

Start by clearing up a common confusion, because many teams think they’ve solved provenance when they’ve only solved inventory. A Software Bill of Materials (SBOM) tells you what’s inside an artifact: “this build contains these components at these versions.” The 2021 US Executive Order’s SBOM mandate did the industry a real service by forcing teams to actually know their dependencies.

But an SBOM has a hard scope limit: it doesn’t tell you whether the artifact was built from the code you think it was, or whether the build process itself was compromised. That’s exactly the gap SolarWinds and GhostAction exploited — the components were “legitimate,” but the build was subverted. As the post-GhostAction consensus puts it: SBOMs tell you what’s inside; provenance proves where it came from and how it was built. Large buyers increasingly demand both. SBOM is the ingredient list; provenance is the tamper-evident seal and the factory record.

Build provenance with SLSA

The framework that defines build provenance is SLSA — Supply-chain Levels for Software Artifacts (pronounced “salsa”), a vendor-neutral OpenSSF project. SLSA answers a precise question that SBOM, VEX, and the NIST SSDF don’t: is the artifact a consumer received the same artifact a build system produced from a specific source under documented controls?

It’s structured as a maturity ladder, which makes adoption incremental rather than all-or-nothing:

Diagram illustrating the SLSA maturity ladder with four levels of provenance: Level 0 (no guarantees), Level 1 (provenance exists), Level 2 (signed provenance), and Level 3 (hardened and isolated build).
  • Level 1 — provenance exists: the build emits a description of how the artifact was made. Not tamper-resistant yet, but you have a record.
  • Level 2 — provenance is signed and produced by a hosted build service, so tampering is detectable.
  • Level 3 — provenance comes from a hardened, isolated build with verified source control, resistant to forgery even by a determined insider.

The provenance itself is a SLSA provenance predicate wrapped in an in-toto attestation (in a DSSE envelope) — capturing builder identity, build instructions, parameters, and dependency digests. In practice it’s a JSON document the build platform writes per release and a verifier reads to make a trust decision:

{
"_type": "https://in-toto.io/Statement/v1",
"subject": [{ "name": "my-artifact", "digest": { "sha256": "abc123..." } }],
"predicateType": "https://slsa.dev/provenance/v1",
"predicate": {
"buildDefinition": {
"buildType": "https://github.com/slsa-framework/slsa-github-generator",
"externalParameters": {
"repository": "https://github.com/org/repo",
"ref": "refs/heads/main"
}
},
"runDetails": { "builder": { "id": ".../generator_generic_slsa3.yml" } }
}
}

The subject.digest binds the attestation to one exact artifact (primitive #1), and the predicate is the attestation of how it was built (primitive #3).

Keyless signing with Sigstore

The signing layer (primitives #2 and #5) is where Sigstore has become the de-facto standard, because it removed the worst part of signing: key management. Its three components:

  • Cosign — signs and verifies container images and artifacts.
  • Fulcio — issues short-lived certificates tied to an OIDC identity (your GitHub, Google, or workload identity) instead of a long-lived key.
  • Rekor — a transparency log that records every signing event.

The magic is keyless signing: you authenticate via OIDC, Fulcio issues an ephemeral certificate bound to that identity, you sign, and the event lands in Rekor — no long-lived private key to store, rotate, or leak. This is why Sigstore adoption spread fast across npm, PyPI, and Kubernetes. (One caution from practitioners: don’t quietly fall back to long-lived static keys without a rotation plan — that reintroduces exactly the risk Sigstore removed.)

The verification gate: “no provenance, no deploy”

Generating provenance is worthless if nothing checks it. The payoff comes at the verification gate, where cloud registries and admission controllers enforce a simple policy: no valid provenance, no deploy. The full pipeline looks like this:

Infographic outlining the software supply-chain provenance pipeline, illustrating steps from source to deployment, including processes for building, signing, and verifying software artifacts.

The verification logic is small but decisive, applied to build integrity:

def admit(artifact, provenance, policy) -> bool:
# 1. integrity: provenance is bound to THIS exact artifact
if provenance.subject.digest.sha256 != sha256(artifact):
return reject("digest mismatch — not the artifact we verified")
# 2. authenticity: signature verifies against a Sigstore identity in Rekor
if not verify_signature(provenance, rekor=True):
return reject("signature/transparency-log check failed")
# 3. policy: built from the source and pipeline we expect
if (provenance.repository, provenance.workflow, provenance.ref) not in policy.allowed:
return reject("unexpected build source — possible tampering")
return True # only now does it deploy

Tooling makes each step turnkey: GitHub artifact attestations generate signed SLSA provenance from Actions; Red Hat’s Konflux issues in-toto attestations tied to policy; and GUAC (Graph for Understanding Artifact Composition) stitches provenance, SBOMs, and attestations into a queryable graph across your whole estate, so you can answer “where is this compromised dependency, and what did it build?” in one place.

A pragmatic adoption roadmap

The specifications are mature and the tooling exists, so the path is well-trodden: start at Level 1 by turning on provenance generation in CI (GitHub artifact attestations are the lowest-friction on-ramp); move to Level 2 by signing with Sigstore and recording in Rekor; target Level 3 for your most critical artifacts with hardened, isolated builds; and add the verification gate so unverified artifacts can’t promote to production. Regulation (EO 14028, the CRA) makes Levels 1–2 effectively table stakes for anyone selling software to regulated buyers.

The same primitives for data and AI models

Everything above is artifact-agnostic, which is why it extends naturally to data provenance. Recall the distinction: provenance (origin, authenticity, trustworthiness) versus lineage (flow and transformation). Apply the same primitives — hash the dataset, sign a manifest attesting its source and collection method, chain the transformations, log it — and you can answer “is this data what it claims to be?” with cryptographic confidence rather than a spreadsheet and good faith.

This matters most for AI, where two provenance questions are now business-critical. First, training-data provenance: what went into the model, and can you prove the rights, consent, and absence of contamination behind it — increasingly a legal and audit requirement. Second, model provenance: a model is itself a supply-chain artifact, so sign your model weights, treat the model card as an attestation, and verify model provenance before loading — the same way you’d verify a container image.

Why detection lost, and provenance won

The instinctive response to deepfakes is detection: build a classifier that spots fakes. That’s a losing battle. Generative models improve continuously, so any detector is perpetually one model version behind, and analysts project synthetic content could reach up to 90% of online media. You cannot win by inspecting the pixels.

C2PA inverts the problem. Instead of detecting fakes after the fact, it proves authenticity at the point of creation. Content that carries valid credentials doesn’t need to be detected as real — it cryptographically proves its origin and edit history. The losing game (spot the fake) becomes a winnable one (verify the genuine). That’s why the US CISA endorsed content credentials as a key countermeasure in its January 2025 advisory on multimedia integrity in the generative-AI era.

C2PA Content Credentials: a nutrition label for media

The Coalition for Content Provenance and Authenticity (C2PA) — with over 6,000 members and affiliates as of January 2026 — produces the open standard now treated as the global reference. Its Content Credentials are often described as a “nutrition label” for digital content, and structurally they’re just primitives applied to a media file:

Diagram explaining C2PA Content Credential, featuring sections on Media file, Assertions, Chain of custody, Signature, C2PA metadata, Invisible watermark, and Fingerprinting.
  • Assertions — the claims: “captured by this camera,” “edited with Photoshop,” “generated by AI model X.”
  • Manifest — a tamper-evident record of the creation history and every edit/transform applied.
  • Signature — a cryptographic signature by the creator or tool, verifiable by anyone (primitive #2).
  • Chain of custody — the full provenance chain from creation through all modifications to the current state (primitive #4), bound to the asset’s hash (primitive #1).

A verifier checks whether the manifest is well-formed, signed by a trusted source, and still bound to the asset. It’s the exact same model — signed, hashed, chained claims — applied to a JPEG instead of a JAR.

Adoption is real in 2026 (and uneven)

Content Credentials moved into production across the whole content pipeline:

  • Capture: camera makers Leica, Nikon, and Canon sign at the hardware level; Canon moved C2PA-compliant capture into newsroom workflows. Devices like Samsung Galaxy S25 and Google Pixel 10 support it natively.
  • Creation/editing: Adobe Content Credentials and Microsoft (auto-labelling AI content in Bing and Designer); Intel is working on chip-level signing.
  • AI generation: OpenAI adds C2PA metadata to generated media and announced a layered approach with SynthID plus public verification; Google has SynthID verification live in Gemini and is expanding C2PA verification across Search and Chrome, with Content Credentials in Google Photos.
  • Distribution: LinkedIn and TikTok display verification icons.

The weak point — and it’s the big one — is preservation. Most social and messaging platforms still strip embedded metadata, and uploads, screenshots, exports, and recompression frequently break it. As of 2026, signed content often arrives at the viewer with its credential gone. C2PA is a strong signal, not a guarantee, when used alone.

Watermarking and durable content credentials

The fix for stripping is defence in depth for media. Because metadata can be removed, you pair it with marks that survive transformation:

  • Invisible watermarking (e.g. SynthID) embeds a signal into the pixels or audio that survives platform transfers, recompression, and many edits.
  • Fingerprinting lets you match content against a registry even with no embedded data at all.

The emerging best practice — and what the EU Code of Practice specifies as multi-layer marking, mapping to a “Durable Content Credentials” architecture — is to combine C2PA metadata + an invisible watermark + (optionally) fingerprinting. Metadata gives you the rich, verifiable manifest when it survives; the watermark gives you a durable fallback when the metadata is stripped. No single layer is foolproof; the stack is what holds up in the wild.

A diagram illustrating the durable content-provenance lifecycle, highlighting four key steps: 1. Create & sign, 2. Distribute, 3. Verify, and 4. Display. The process emphasizes the importance of watermarking and metadata in content credibility.

The compliance mandate

This is where the regulatory clock becomes a concrete engineering requirement for anyone shipping AI features:

  • EU AI Act Article 50, enforceable August 2, 2026, requires deployers to disclose AI-generated or manipulated content using both visible markings and machine-readable metadata — which is precisely the C2PA-plus-watermark stack.
  • California SB 942 (AI Transparency Act) took effect January 2026; the New York Stop Deepfakes Act and others are arriving.

If your product generates or significantly manipulates content for public distribution, labelling it with durable provenance is now a legal obligation, not a nice-to-have. The compliance clock is already running.

The honest limits (read this before you trust a checkmark)

A responsible provenance implementation is defined as much by what it doesn’t claim as what it does. Four limits matter:

  1. Provenance certifies history, not truth. This is the most acute for media. A credential proves a device signed a file and it wasn’t altered since — it cannot verify that the camera was pointed at what the caption claims, that the scene wasn’t staged, or that the content is used in good faith. A credential establishes that a claim was made, not that the claim reflects reality.
  2. Metadata stripping is endemic. Until platforms preserve credentials end to end, expect them to vanish in transit — which is why the watermark layer isn’t optional.
  3. Adoption is incomplete. C2PA is necessary but structurally insufficient in isolation; treat it as one signal among several, not proof.
  4. Provenance can carry privacy risk. Identity assertions in a manifest can create surveillance exposure — who created what, when, where. Balance disclosure against the creator’s privacy, and prefer minimal or pseudonymous assertions where identity isn’t required.

Build with these in mind and you get genuine value; ignore them and you’ll either over-trust a green badge or leak creator identity.

The builder’s playbook, and the whole picture

For an AI or content product in 2026, the practical implementation is: sign at creation (embed Content Credentials), add a durable invisible watermark, verify on ingestion and display, surface the “nutrition label” in your UI so users can inspect provenance, and treat the result as a signal, not a verdict — combined with other context, never as sole proof of truth. For generative features specifically, labelling output this way is how you meet Article 50.

Software, data, and AI-generated content all rest on the same five primitives: hash the artifact, sign it with an identity, attest to its origin and history, chain the modifications, and log it so anyone can independently verify. Implicit trust is gone across all three domains for the same reason — fakes became free — and verifiable provenance is the replacement. As of 2026 it’s simultaneously a trust differentiator and a hard compliance requirement, and the engineering is mature enough that the question is no longer whether to adopt it but how fast.

The throughline for developers is a single habit: sign what you produce, and verify what you consume — whether it’s a container image, a dataset, a model, or a video. That habit, applied consistently, is what rebuilds trust in a world where nothing can be trusted on sight.

Pre-emptive Cybersecurity

Security has one brutal piece of arithmetic at its core: defenders must be right every time; attackers only need to be right once. For decades the response to that asymmetry was reactive — build taller walls, install faster alarms, and when something gets through, detect and respond. Detection-and-response (D&R) is the model that gave us SIEMs, SOCs, EDR, and the entire incident-response playbook. It works by waiting for an attack to begin, then reacting.

In 2026, that model is buckling, and the reason is speed.

Machine-speed attacks broke the reactive window

The reactive model depends on a window: the time between an attack starting and a defender responding. That window has now collapsed toward zero, because attackers have AI too.

The numbers tell the story. Roughly 40,000 new CVEs were logged in 2024 alone — a 38% jump over the prior year — and adversaries now use generative AI to chain those flaws into attacks at machine speed, weaponising exposed services and misconfigurations within minutes of discovery. As one industry forecast put it bluntly: “AI-fueled attacks start and end before a ticket is even created.” When the attack completes faster than your SOC can open a case, faster alarms don’t help. You can’t respond your way out of an attack that’s already over.

The crucial nuance — and it’s good news for defenders — is that AI mostly isn’t creating brand-new attack vectors; it’s supercharging the speed and volume of existing ones. That means the fundamentals still work. What has to change is when you apply them. If you can’t win the race to respond, you have to win before the race starts.

What “pre-emptive” actually means

This is the shift the industry is now naming pre-emptive cybersecurity — and it’s not just a marketing rebrand. Gartner has formalised it as a primary strategic technology trend for 2026 and projects that about 35% of cybersecurity solutions may be pre-emptive by 2028.

Pre-emptive cybersecurity is a proactive approach that identifies, predicts, and neutralises potential threats before they can execute an attack. The analogy that captures it: reactive security is a smoke detector and a fire extinguisher; pre-emptive security is fireproofing the house, so the fire either never starts or gets snuffed out while it’s still an ember. You act on the early warning signs and the exploitable conditions before the adversary moves, rather than responding after.

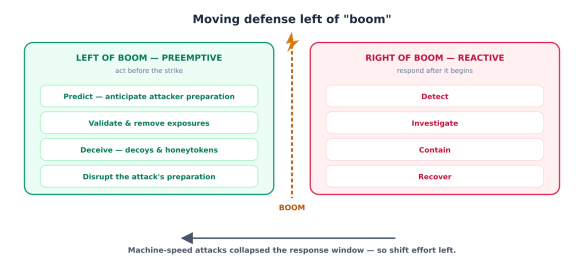
Diagram illustrating preemptive and reactive strategies for cybersecurity. Left side labeled 'Left of Boom - Preemptive' includes actions like predict, validate, deceive, and disrupt. Right side labeled 'Right of Boom - Reactive' includes actions like detect, investigate, contain, and recover. Central 'BOOM' signifies the moment an attack occurs, with a note on machine-speed attacks collapsing response windows.

Security people call the moment of compromise “boom.” Reactive security lives right of boom — everything after the attack begins. Pre-emptive security moves the work left of boom — into the period when, as the framing goes, cyberattacks aren’t random: attackers research their targets, test methods, and build tools before they strike. That preparation phase is an opportunity, and pre-emptive defence is about exploiting it.

Proactive vs. pre-emptive: the validation distinction

Here’s a distinction worth getting right, because it separates the real thing from the hype. “Proactive” and “pre-emptive” are not synonyms. Plenty of tools are proactive — they scan for vulnerabilities, flag misconfigurations, and produce long lists of theoretical risk. The trouble is that a list of 40,000 possible problems isn’t a defence; it’s a different kind of alert fatigue.

Gartner draws the line at validation. Security becomes genuinely pre-emptive only when it validates real attack feasibility — confirms that a given exposure could actually be exploited in your environment — and then mobilises mitigation before impact. Without that validation and early action, you’re proactive at best: busy, but not safe. Validation is the inflection point, and it’s exactly the step AI makes fast enough to matter.

The framework: Deny, Deceive, Disrupt

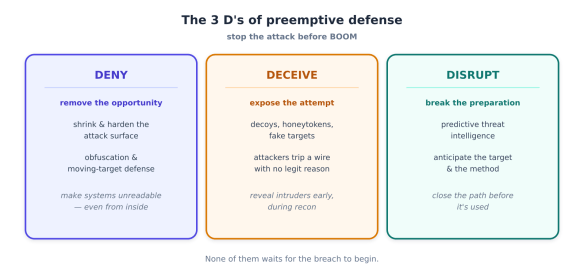
Pre-emptive cybersecurity organises around three strategies — the “3 D’s” — each aimed at stopping an attacker before they can execute.

Infographic outlining the 3 D's of preemptive defence: Deny, Deceive, and Disrupt. Each section details strategies to stop attacks before they occur, including methods like hardening attack surfaces and using predictive threat intelligence.
  • Deny — make the attacker’s job impossible by removing what they need. This is exposure management (find and eliminate the exploitable weaknesses) plus obfuscation and moving-target techniques that make systems unreadable or invisible to unauthorised users — mitigating even ransomware and APTs that have already gotten inside, because there’s nothing legible for them to exploit.
  • Deceive — seed the environment with decoys, honey tokens, and fake targets. An attacker probing your network trips a tripwire that has no legitimate reason to be touched, revealing themselves early and wasting their effort on a phantom.
  • Disrupt — use predictive threat intelligence to anticipate the attack and interfere during its preparation phase: pre-empting an exploit before it’s weaponised against you, disrupting infrastructure, or closing the validated path the attacker was about to use.

Deny removes the opportunity, Deceive exposes the attempt, Disrupt breaks the preparation. None of them waits for boom.

Why this needs AI (and why now)

You might reasonably ask: if attackers research and prepare before striking, why hasn’t pre-emptive defence always been the norm? Because at human speed it was impossible to keep up. Validating which of 40,000 CVEs are actually exploitable in your environment, continuously, across a sprawling multi-cloud and SaaS estate — and then remediating before an adversary weaponises them within minutes — is not a human-scale task. It’s the AI uplift that makes pre-emptive defence practical in 2026: AI is what compresses “validate the exposure” from weeks to hours, and “decide what to fix first” from a guessing game to a ranked, evidence-backed plan.

Attackers got faster with AI; defenders match them not by responding faster (a race they’ll lose) but by moving the fight left of boom with AI.

From CTEM to pre-emptive exposure management

The foundation is Continuous Threat Exposure Management (CTEM) — the Gartner-defined discipline of continuously discovering and prioritising exposures rather than running periodic scans. CTEM was a real advance, but it has a gap: even mature CTEM programs discover and prioritise faster than they can remediate. You end up with an excellent, continuously-updated list of problems and a remediation backlog that adversaries outrun.

Pre-emptive Exposure Management (PEM) closes that gap. It unifies three things into one automated loop — continuous discovery, risk-based validation, and automated remediation — with the explicit objective of shrinking the remediation gap toward zero: exposures removed before threat actors can reach them.

Diagram illustrating the preemptive exposure pipeline: stages include Discover, Validate, Prioritize, and Remediate with notes on attack surface and remediation strategies.

The pipeline has four stages, and the second one is where pre-emption is won or lost:

  1. Discover — continuously inventory assets, exposures, and the attack surface across endpoint, cloud, SaaS, and the software supply chain. With ~40,000 new CVEs a year, discovery is necessary but produces overwhelming volume.
  2. Validate — AI confirms whether each exposure is actually reachable and exploitable in your specific environment, using attack-path analysis and breach-and-attack simulation. This is the step that turns “40,000 theoretical problems” into “the 50 an attacker could actually use against us.” One vendor reports AI cutting attack-surface validation from weeks to hours.
  3. Prioritise — rank the validated, reachable exposures by business impact and real exploitability, not raw CVSS score. A “critical” CVE on an unreachable asset matters less than a “medium” on the path to your crown jewels.
  4. Remediate — automatically fix, virtually patch, or harden the prioritised exposures before exploitation. After years of caution, automated remediation is getting the go-ahead in 2026, because the alternative — manual patching at human speed — loses to machine-speed weaponisation.

Conceptually, the loop gates on validation rather than firing on every finding:

def preemptive_loop(environment):
for exposure in discover(environment): # continuous, high-volume
reachable = validate_exploitability(exposure, environment) # the inflection
if not reachable:
continue # de-prioritise: not a real path
risk = score(exposure, blast_radius(exposure, environment)) # impact, not CVSS
if risk >= AUTO_REMEDIATE_THRESHOLD:
remediate(exposure) # fix / virtual-patch before boom
else:
queue_for_review(exposure, risk) # human triage for the rest

Note what validation buys you: the expensive remediation effort is spent only on exposures that are real attack paths, not on the long tail of theoretically-scary-but-unreachable findings that drown traditional vulnerability management.

The techniques, mapped to the 3 D’s

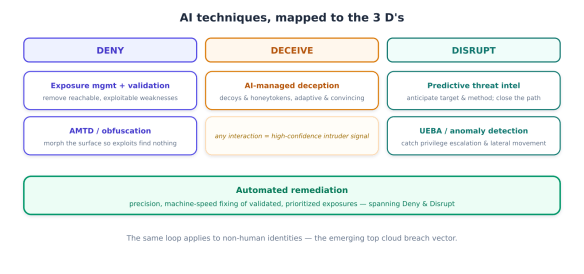
Exposure management is the backbone, but the full pre-emptive toolkit spans all three strategies. Here’s how the AI techniques line up.

Diagram illustrating AI techniques categorised into Deny, Deceive, and Disrupt, with descriptions of strategies under each category.

Deny — remove the opportunity:

  • AI-driven exposure management with validation (the pipeline above) eliminates the exploitable weaknesses before attackers reach them.
  • Automated Moving Target Defence (AMTD) and obfuscation continuously morph the runtime attack surface — memory layout, application structure — so that even a working exploit finds nothing where it expects it. This is the “make systems unreadable” leg of Deny, and it mitigates ransomware and APTs even when the attacker is already inside, because there’s no stable target to exploit.

Deceive — expose the attempt:

  • AI-managed deception seeds the environment with decoys and honey tokens that legitimate users have no reason to touch. AI makes the decoys convincing and adaptive, and any interaction is high-confidence evidence of an intruder — caught during reconnaissance, long before impact.

Disrupt — break the preparation:

  • Predictive threat intelligence models attacker behaviour and infrastructure to anticipate what will be targeted and how, so you can close the path the adversary was about to use. This is the “attackers research and build before they strike” window, turned into a defensive advantage.
  • Behavioural analytics (UEBA) and anomaly detection baseline normal behaviour for users, machines, and — increasingly — non-human identities, then flag the deviations that precede damage: privilege escalation, anomalous identity behaviour, lateral movement. Catching the precursor behaviour is pre-emption applied to an attacker who’s already gotten a foothold.

Spanning Deny and Disrupt: automated remediation. Once an exposure is validated and prioritised, AI agents perform precision remediation — patch, virtual-patch, reconfigure, or revoke — at machine speed, closing the gap before it’s exploited.

The non-human-identity front

One area deserves a specific call-out because forecasts converge on it: machine identities are becoming the top cloud breach vector. Every service, workload, and AI agent is a non-human identity (NHI) with credentials, and NHIs now sprawl faster than humans can govern them. The pre-emptive answer is the same loop applied to identity: continuously discover NHIs, validate which have excessive or exploitable permissions, prioritise by what they can reach, and automatically remediate — tightening scopes and revoking standing access before an attacker (or a hijacked agent) abuses them.

The limits

Pre-emptive defence is powerful, not magical, and two cautions keep it credible. First, validation quality is everything — a pre-emptive program that miscalibrates exploitability will either drown you in false “reachable” findings or auto-remediate things that didn’t need it (and auto-remediation can break production, so the threshold for autonomous action must be set conservatively and the rest routed to humans). Second, pre-emption complements rather than replaces detection-and-response; you still need eyes right of boom for the attacks that slip the net. The shift is one of emphasis and timing — moving the centre of gravity left — not an abandonment of the reactive stack.

Why the SOC had to change too

The reactive operations centre is breaking with it. Traditional SOCs drown in alert fatigue, stitch together fragmented tools, and triage by hand — and the gap between attack speed and response speed is exactly where breaches happen. Telemetry grows faster than budgets, so teams filter data before ingestion just to control cost, dropping the very signals an attacker exploits. You cannot run a machine-speed, left-of-boom defence on a human-speed, tool-sprawled SOC.

Platformisation: SIEM becomes the orchestration layer

The first half of the answer is architectural consolidation. The old stack — separate SIEM, XDR, SOAR, threat intel, and exposure management products — is converging into unified platforms built on a shared data layer. SIEM itself is transforming: not dying, but evolving from passive log storage into the AI-driven orchestration layer for unified detection, investigation, and response. The modern SIEM market reflects the momentum, projected to grow from £5.58 billion in 2024 to £10.05 billion by 2029.

The consolidation is visible in the market moves: Palo Alto absorbed IBM QRadar SaaS customers into Cortex XSIAM; Google expanded Chronicle into Google SecOps; Microsoft unified Sentinel with Defender and Security Copilot. The buyer’s advantage is real — converged platforms eliminate separately licensing SIEM, XDR, and SOAR, and cut the integration overhead of bolting tools together. The evaluation rule that matters: look for platforms where detection, investigation, and response share a unified data layer, not capabilities stitched across product tiers.

The structural enabler underneath is data normalisation. The Open Cybersecurity Schema Framework (OCSF) — now under the Linux Foundation — provides vendor-agnostic schema standardisation, which makes federated search, cross-platform correlation, and portable detection rules possible regardless of which platform you run. The principle is simple and important: AI-driven detection only works when data is normalised across sources. Garbage-in still applies, and OCSF is how you avoid it.

The agentic SOC

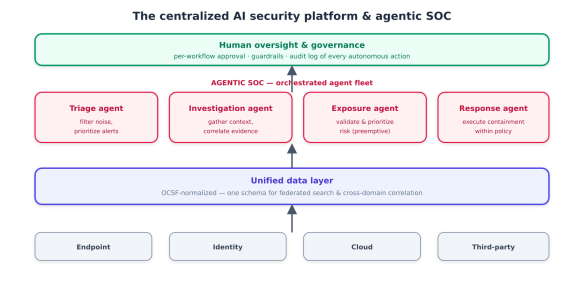
The second half of the answer is the agentic SOC. An agentic SOC deploys autonomous AI agents that triage alerts, investigate incidents, correlate evidence across identity/endpoint/cloud, verify suspicious activity, and execute response actions — reasoning through novel scenarios rather than just running pre-written SOAR playbooks.

Diagram illustrating a centralized AI security platform and agent-centric Security Operations Centre (SOC) structure, featuring components such as human oversight and governance, triage, investigation, exposure, and response agents, along with a unified data layer for integrated security management.

The platform incumbents have all built toward this:

  • CrowdStrike Charlotte AI orchestrates a fleet of purpose-built agents (triage, investigation, exposure prioritisation, and more) via Charlotte Agentic SOAR, with AgentWorks letting teams build custom agents in natural language — explicitly “always under human control,” with per-workflow oversight and audit logging.
  • Palo Alto Cortex XSIAM / AgentiX consolidates endpoint, network, cloud, identity, and third-party data on the Cortex data lake.
  • Microsoft Sentinel + Security Copilot and Google SecOps (with Gemini) take the same unified-platform approach.
  • SentinelOne Purple AI layers agentic investigation over hyper automation, reporting 63% faster detection and 55% faster remediation, with 70% better platform-management efficiency.

The market has crystallised into recognisable architecture models: a single-agent copilot embedded in a platform (Charlotte), a multi-agent mesh of collaborating specialists, a hyper-automation-layered approach (SentinelOne), and a hybrid human-AI model where AI triages and humans own the last mile. Which one fits depends on your team’s maturity and existing stack — but every credible one keeps humans in command.

The autonomy spectrum — and keeping humans in command

The most important design decision in an agentic SOC isn’t which vendor; it’s how much autonomy you grant, on which actions. The field runs along a clear spectrum, and the right answer is rarely the far end.

Diagram illustrating the SOC autonomy spectrum with three categories: AI-Augmented, Semi-Autonomous, and Fully Agentic, highlighting the roles of AI and humans in decision-making processes.

The pattern that works mirrors the human-checkpoint discipline from across this whole library: AI handles the high-volume, repetitive work — filtering noise, correlating signals, triaging alerts, executing routine, pre-approved response — and humans own the judgement calls and the last mile, especially irreversible containment. The stated goal of every serious platform is to make analysts more effective, not absent: a team that operates at higher scale without higher headcount, not a team that’s been automated away. Tier the autonomy by blast radius — generous on reversible, low-risk actions; mandatory human approval on high-impact ones — and log every autonomous action for audit. (And remember: an agentic SOC is itself an agent system, so everything — least privilege, governance, decision-level audit — applies to your defenders too.)

The catch: consolidation and lock-in

We have to name the trade-off, because the consolidation that delivers the efficiency also concentrates risk. Analysts compare the current moment to the CASB and SASE waves of 2018–2020 — a category “graduating from venture experiment to enterprise category,” consolidating around a small number of well-funded players, with acquisitions of the independents widely expected. The convenience of a single converged platform comes with vendor lock-in: a deeply integrated agentic SOC is, in one analyst’s words, “an ecosystem play, not a vendor-agnostic one,” and its value can diminish sharply in a multi-vendor environment where the agents can’t reach across stacks.

The practical hedges are worth building in from the start:

  • Insist on OCSF-normalised data so your telemetry and detection logic stay portable if you change platforms.
  • Keep an integration path for existing tools rather than ripping-and-replacing everything into one vendor.
  • Validate at your real data volume and on your oldest assets before committing — converged pricing and agent performance both change at scale.
  • Watch the build-vs-buy line: some teams are building custom in-house AI security tooling precisely to avoid lock-in and tailor to their environment.

Consolidation is the right default for most teams — the efficiency and the unified data layer are genuinely how you achieve machine-speed defence — but go in with eyes open about the dependency you’re taking on.

The whole picture

Attacks went machine-speed, so reactive defence lost its window, and the answer is to move left of boom with pre-emptive defence built on the 3 D’s. AI executes that defence through a continuous discover–validate–prioritise–remediate loop plus deception, moving-target defence, and predictive intelligence. And all of it converges onto centralised, AI-native platforms with a unified data layer and an agentic SOC, where AI agents run the high-volume work at machine speed and humans stay in command.

The strategic truth underneath is simple: you fight AI-speed offence with AI-speed defence, applied before the strike rather than after it. The teams that win the next few years won’t be the ones with the fastest alarms. They’ll be the ones who moved the fight left of boom, validated what actually matters, automated the remediation of it, and kept human judgement exactly where the stakes are highest.